Three-Environment Kubernetes Platform
dev, staging and production RKE2 clusters on bare vSphere, with VIP failover proved by forcing a leadership transfer rather than assuming one.
Three RKE2 clusters (15 nodes) on bare vSphere with control-plane VIPs, provisioned from the API, with failover proven by forcing a leadership transfer.
- Role
- Solo: designed, provisioned and operate
- Timeframe
- Sep 2026 to present
- clusters built 20 Sep 2026
- Team
- 1
- Problem
- A single cluster is not a platform. Dev, staging and production need to exist separately, be rebuildable, and survive losing a control-plane node.
- Approach
- Nodes created with govc and cloud-init through guestinfo, kube-vip for the API, Cilium, ingress on pinned NodePorts, restore-tested etcd and token backups, and a failover test that was redone after the first one proved nothing.
- Result
- 15 of 15 nodes Ready, VIP moved in about 3 seconds under a real transfer, etcd fsync p99 inside budget and trended. One constraint stated plainly: the three share one VLAN.
Every figure above is measured or read from the running system. Where a figure has a source line, that is how and when it was read.
Technology Stack
What it is
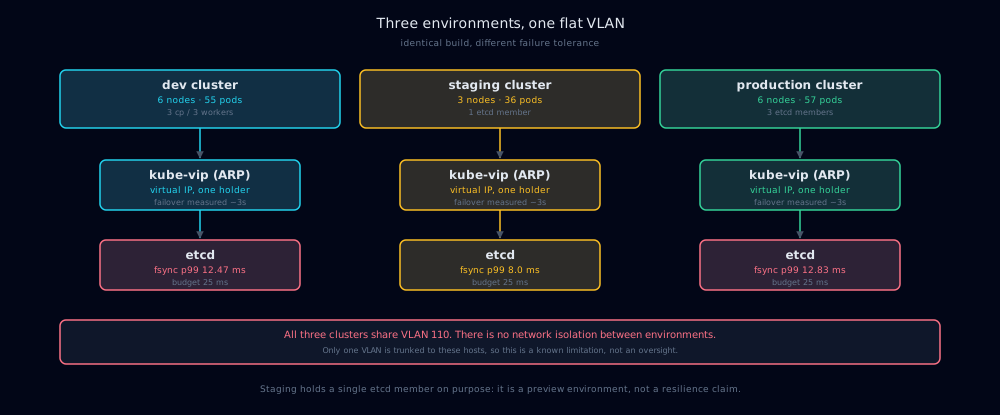
Three RKE2 clusters on the vSphere lab: development (6 nodes), staging (3), and production (6 nodes with a 3-member etcd quorum). Each has a kube-vip control-plane VIP and its own ingress controller. Nodes are provisioned from the vCenter API with cloud-init through guestinfo. No DHCP, no manual installs.
Production runs behind a Cloudflare tunnel, so there are no inbound ports on the network at all.
The failover test that first gave a false pass
The obvious way to test a control-plane VIP is to stop the API server on whichever node holds it. I did that, the API recovered in about a second, and the test looked green.
It was meaningless. kube-vip runs as a DaemonSet with its own leader election, so stopping the API server left the VIP exactly where it was. The address never moved and nothing about failover had been exercised. The same trap as deleting a pod that a DaemonSet recreates in seconds.
Deleting the kube-vip pod on the holder forced a real leadership transfer: the VIP moved from control-plane node 1 to node 3 in roughly three seconds, the API stayed reachable through the VIP throughout, and exactly one node held the address afterwards. That last check matters in both directions: zero holders is an outage, two or more is a split brain.
That test was also wrong, in a way I only found on 8 October. It polled the API with certificate verification switched off, so it could not see that node 3 was serving a certificate without the VIP in it. Nodes 2 and 3 had been joined without the tls-san block. When kube-vip moved the address to node 3 on its own on 29 September, every kubeconfig started failing x509 and stayed that way for 9 days, 8 hours and 43 minutes. Both control planes now carry the VIP in their certificates, the watchdog checks every control plane for it, and the failover probe verifies certificates. Full write-up in the blog post linked from the metric above.
Four provisioning traps, all of which looked like something else
The first staging VMs booted cleanly, reported healthy VMware Tools, and had no IP address. Four separate defects were hiding behind that one symptom.
govc's vm.create defaults to an E1000 adapter, which enumerates as ens160 while the netplan targeted ens192. The -disk 0 form segfaults govc outright; the supported form is -disk <path> -link=false. datastore.cp will not create its target directory, and vm.destroy removes it, so a recreate fails on a missing path.
The real one was firmware. The Ubuntu cloud image has no EFI system partition, so an EFI virtual machine boots to an empty device list and never reaches the disk. The working nodes were BIOS. vm.change has no firmware flag, so fixing it meant destroy and recreate.
I found it by diffing a broken VM against a working one field by field, after a console screenshot showed Ubuntu booting fine with the hostname applied, which proved cloud-init had run and narrowed the fault to networking alone.
A constraint I could not engineer around
The design called for separate subnets per environment. Only one VLAN is trunked to the hosts, and new port groups would need physical switch and router changes I could not make remotely.
So the three clusters share a single L2 segment with IP-range separation instead. That is worth stating plainly rather than hiding: dev, staging and production are not network-isolated from each other. It is documented as a known limitation to revisit before production carries anything sensitive.